Let us know how we can help
Sales & Pricing
Speak to a rep about your business needs

Help & Support
See our product support options
General inquiries and locations
Contact us

 Control-M + Hadoop MapReduce
Your Hadoop MapReduce workflow starts before the program JAR ever executes — and it can fail when something upstream breaks. An HDFS input file that arrives incomplete. A Sqoop import that finishes late. Control-M orchestrates the full chain: HDFS data arrival, Sqoop ingestion, MapReduce execution, and downstream Hive processing.
common workflow issues
Does this sound like your week?
These aren’t edge cases. They’re the normal operating conditions for teams running Hadoop MapReduce jobs across multiple tools. Here’s how Control-M handles each one.
INPUT READINESS
Your 2 a.m. MapReduce job started. The HDFS input never arrived.
Control-M HDFS File Watcher waits for the required file and minimum file size before completing successfully. The MapReduce job can remain dependent on that event, preventing premature execution against missing or incomplete input data.
FAILURE RECOVERY
The MapReduce job failed. Your downstream Hive processing is still waiting.
Control-M places MapReduce and downstream Hadoop jobs in the same dependency chain. Failed processing prevents dependent jobs from being released until defined recovery conditions are satisfied, containing the failure instead of propagating bad data downstream.
PIPELINE TIMING
Sqoop finished early. MapReduce still waits for its scheduled start time.
Control-M coordinates Sqoop and MapReduce through workflow dependencies rather than isolated schedules. When the upstream job satisfies its completion conditions, processing can move to the MapReduce stage without waiting for a separate fixed-time scheduling window.
HDFS PREPARATION
Yesterday’s HDFS output remains. Tonight’s MapReduce run cannot safely start.
Control-M supports HDFS pre- and post-commands around MapReduce execution for preparation and cleanup. Configurable command-failure handling determines whether a failed command stops the job, giving teams explicit control over unsafe execution conditions.
SLA RISK
MapReduce is running long. Your morning analytics delivery is now at risk.
Control-M can attach an SLA job to Hadoop workloads and manage MapReduce within the wider dependency chain. Data teams can track schedule-sensitive processing as part of the end-to-end workflow instead of monitoring an isolated cluster job.
Control‑M + Hadoop MapReduce
Control‑M + Hadoop MapReduce
|
workload.types |
Java MapReduce · MapReduce Streaming · HDFS Commands · HDFS File Watcher · Hive · Pig · Sqoop · Spark · DistCp · Oozie · Impala · Distributed Shell · Tajo |
|
trigger.type |
HDFS file arrival · minimum file size · time schedule · upstream job completion · Control-M dependency condition |
|
cross_tool.deps |
HDFS File Watcher · Sqoop · Hive · Pig · Spark · Oozie · DistCp · Impala · Distributed Shell · Tajo · enterprise Control-M jobs |
|
cloud.platforms |
Self-managed Hadoop clusters · Linux execution hosts · on-premises environments · hybrid enterprise workflows (for managed cloud Hadoop, see Azure HDInsight and AWS EMR integrations) |
|
error_handling |
pre-command failure handling · post-command failure handling · dependency control · HDFS File Watcher timeout · SLA job monitoring |
|
throughput |
distributed large-data processing · cluster-based execution · parallel MapReduce workloads · high-volume batch processing |
|
observability |
centralized Hadoop job monitoring · workflow dependency visibility · SLA job tracking · Control-M Monitoring domain |
end-to-end orchestration
One production workflow. Every tool in the stack.
Control-M orchestrates workflows across Hadoop MapReduce, HDFS, Sqoop, Hive, Spark, Oozie, and file transfers in a single job flow — with dependency tracking, SLA visibility, and automated recovery across all of them.
- Cross-tool dependency: HDFS file → Sqoop → Hadoop MapReduce → Hive → analytics handoff
- Data-aware triggers: HDFS file arrival, upstream completion, file-size criteria, processing result
|
Hadoop MapReduce |
Program JAR execution · main class and arguments · HDFS pre/post commands · dependency orchestration |
|
HDFS |
file arrival detection · minimum-size criteria · HDFS commands · preparation and cleanup |
|
Sqoop |
import/export jobs · job arguments · HDFS integration · dependency coordination |
|
Hive |
Hive job execution · scripts and parameters · upstream/downstream dependencies |
|
Spark |
Python jobs · Scala/Java jobs · Spark options · dependency coordination |
|
Oozie |
workflow submission · job properties · workflow extraction · dependency coordination |
|
DistCp |
distributed copy · source/target paths · transfer options · workflow dependencies |
airflow coexistance
Control‑M doesn’t replace your Airflow DAGs. It runs the layer above them.
The objection is common: “We’re already on Airflow.” The issue isn’t what Airflow does – it’s what happens before and after Airflow runs. That’s where pipelines actually fail.
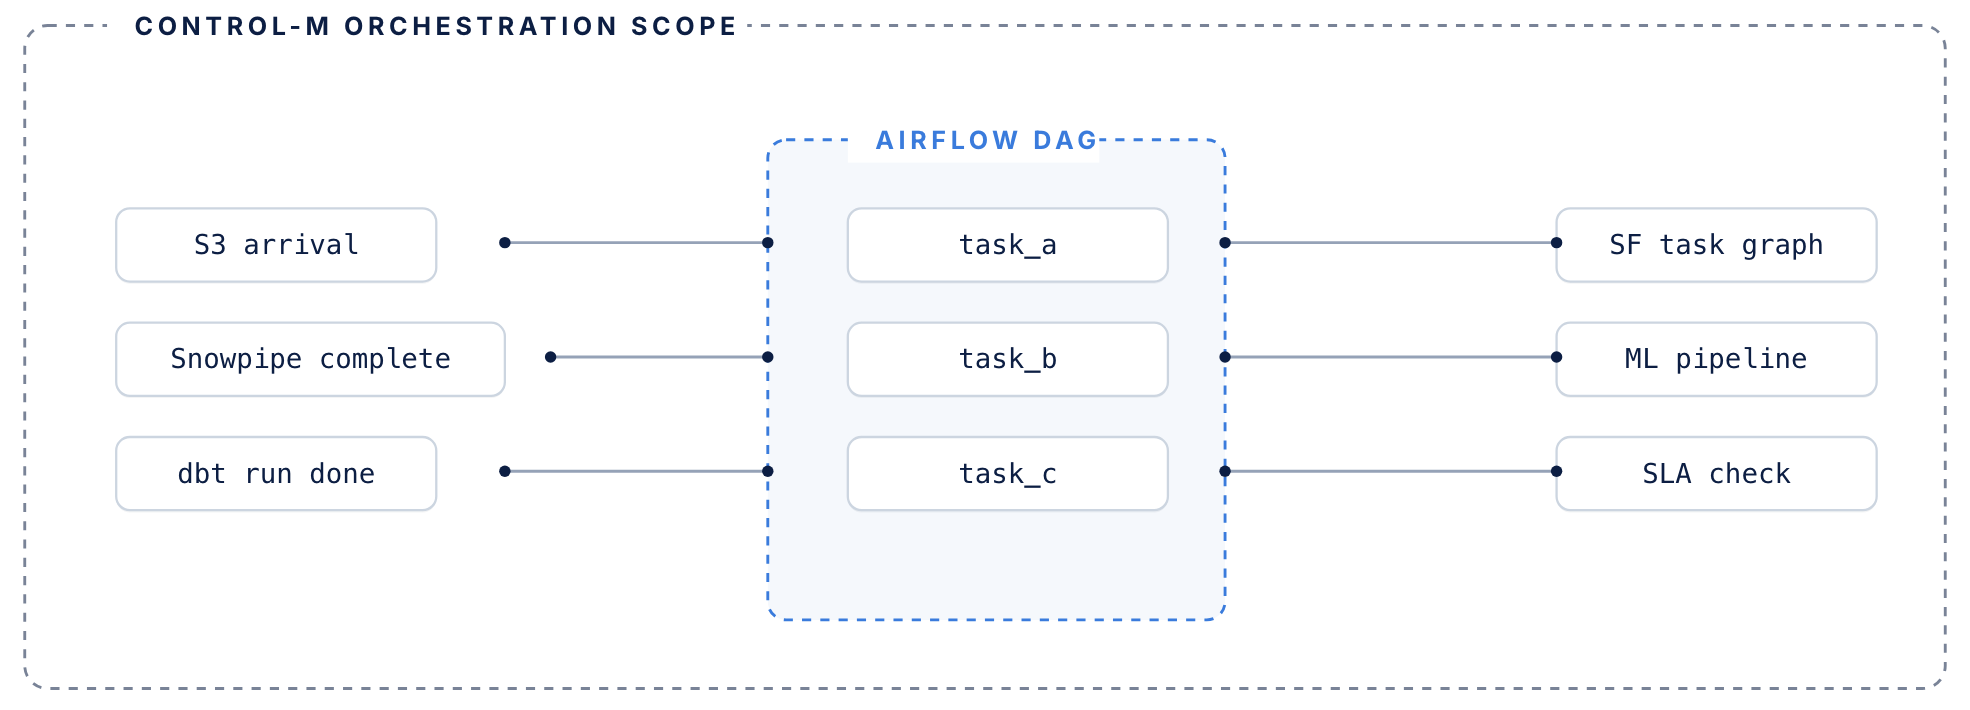
Airflow manages its DAG. Control-M manages everything surrounding it.
airflow handles
DAG-level orchestration inside the data pipeline
- DAG-level task orchestration within data pipelines
- Python operators, sensors, and task dependencies
- Execution graph for jobs that run inside your pipeline
- Manages retries within a single DAG context
control-m adds
The coordination layer around your DAGs
- Coordination layer around DAGs — triggers Airflow based on upstream conditions: file arrivals, API events, other tool completions
- Tracks each DAG’s SLA contribution across the full end-to-end workflow, not just its own routine
- Manages failure recovery when upstream dependencies fail before Airflow even starts
- Existing DAGs don’t need to be rewritten or migrated
MONITOR PIPELINES
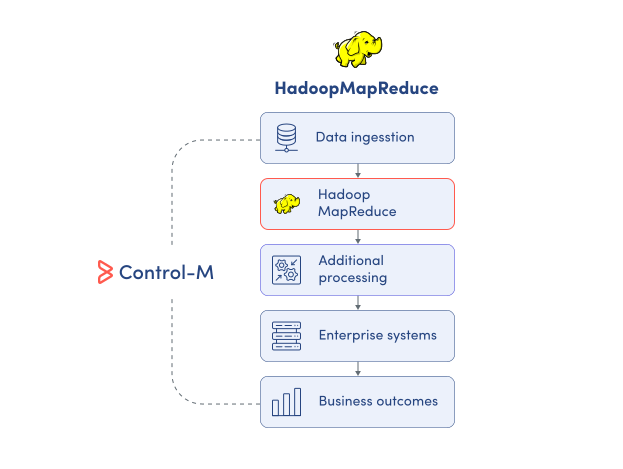
Monitor Hadoop MapReduce jobs across complete data pipeline
Hadoop exposes execution inside the cluster, but production pipelines extend beyond a single MapReduce job. Control-M centralizes MapReduce and surrounding workloads so data teams can monitor processing in the context of the complete workflow:
-
MapReduce execution status
-
Upstream and downstream dependencies
-
Cross-platform workflow visibility
-
Hadoop job monitoring
-
End-to-end processing status
SLA ASSURANCE
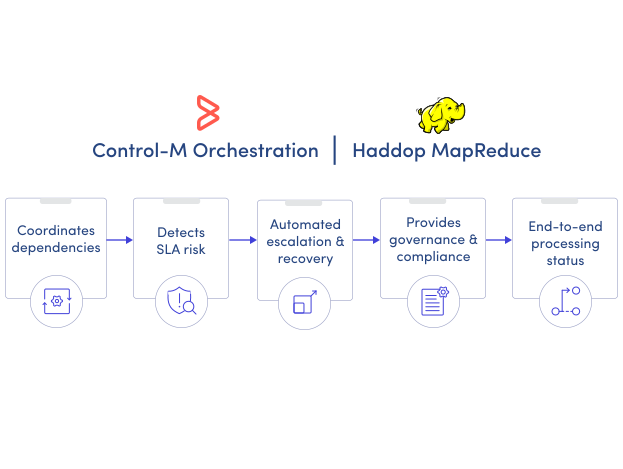
Keep MapReduce processing aligned with delivery SLAs
A successful MapReduce job does not guarantee the complete data service finishes on time. Control-M connects Hadoop processing to enterprise scheduling, dependencies, and SLA management so teams can manage time-sensitive delivery across the full pipeline:
-
Hadoop SLA job tracking
-
Advanced scheduling criteria
-
Complex dependency management
-
Resource pool controls
-
End-to-end SLA visibility
Bring order to complex workflows
Learn how Control-M helps teams orchestrate complex processes with greater visibility, coordination, and control.
